


Top Stories
Artificial IntelligenceLocal LLM Serving at Scale with vLLM, SGLang, and Ollama for Concurrent Production Workloads
Artificial Intelligence
Local LLM Serving at Scale with vLLM, SGLang, and Ollama for Concurrent Production Workloads
Latest
View All NewsLatest Stories
Programming
Node.js 24 LTS vs Bun 1.2 with Production Memory Ceilings, Cold Starts, and Native C++ Addon Stability
An engineering evaluation of V8 13.x default type-stripping execution, native SQLite, JavaScriptCore memory pressure, and N-API crash boundaries under sustained enterprise loads.
Abhijit11 min read
Technology
Wi-Fi 7 Router Guide for India: 6 GHz Spectrum, MLO Latency, and Brick-Wall Penetration
Deconstructing the WPC 5925–6425 MHz de-licensing notification, Wi-Fi 7 vs Wi-Fi 6 performance, and why concrete walls challenge theoretical 320 MHz throughput.
Abhijit10 min read
Cybersecurity
MCP Tool Poisoning and Prompt Injection in AI Agents: Threat Modeling, Vector Exploitation, and Defense-in-Depth Mitigation
How adversarial metadata in Model Context Protocol tools hijacks autonomous agent planners, why high-reasoning models are most vulnerable, and the production gateway patterns needed to stop arbitrary tool execution.
Abhijit11 min read
Reviews
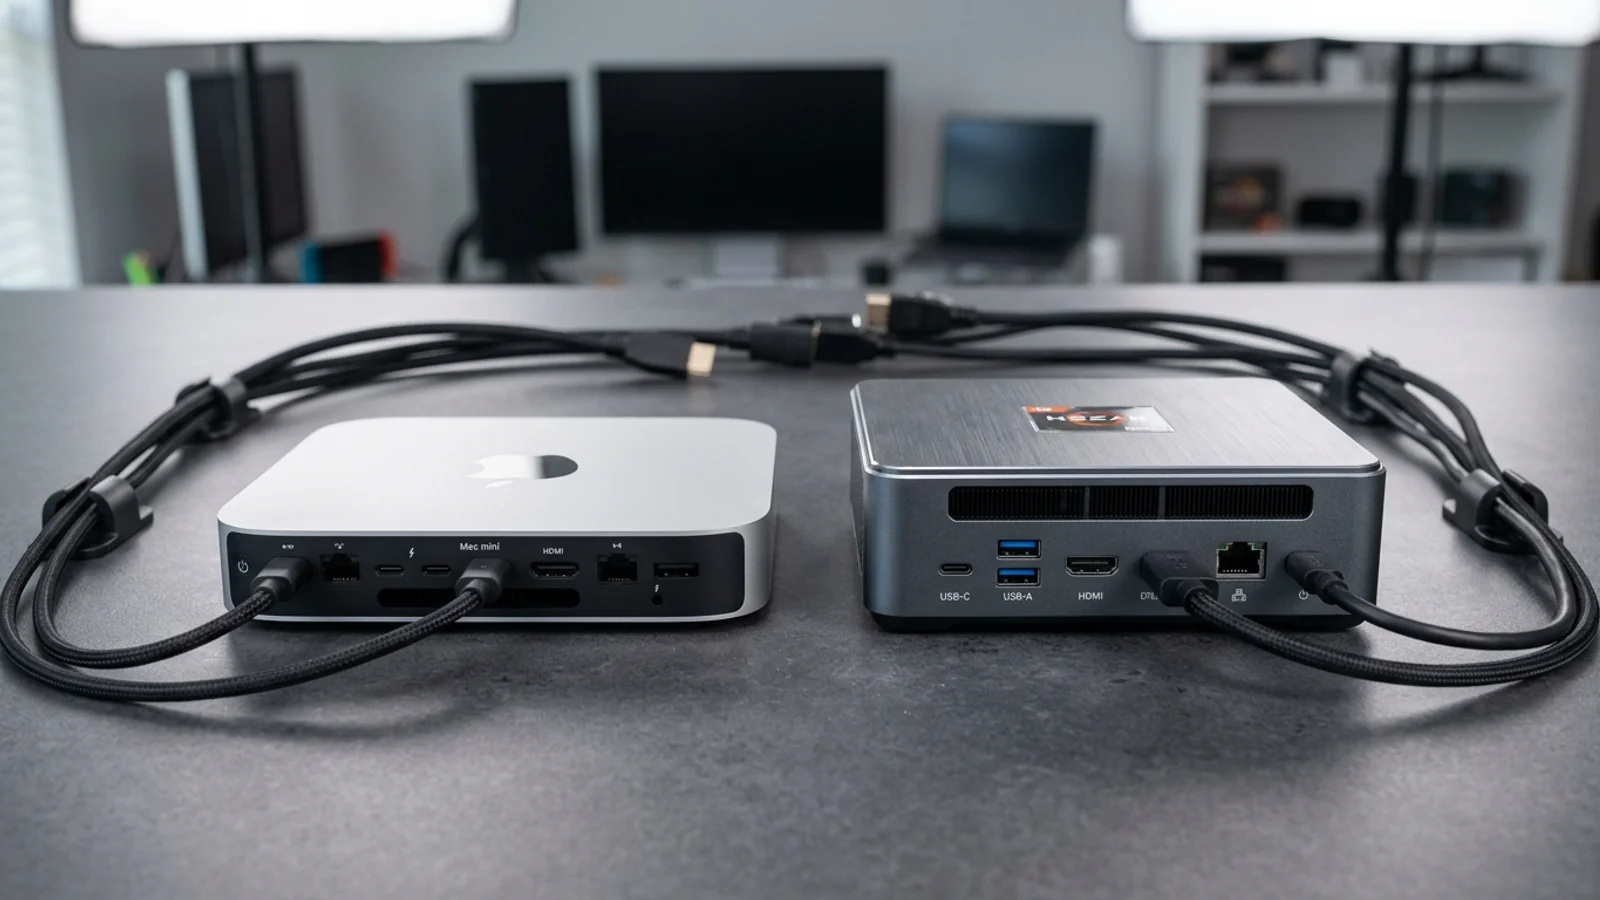
Mac mini M4 vs AMD Ryzen Mini PC for Local AI: Review, Specs, and LLM Inference Benchmarks
A direct lab evaluation comparing Apple Silicon unified memory throughput against AMD Strix Point and Hawk Point mini PCs for local LLM inference, quantized model capacity, and sustained thermal throttling.
Abhijit11 min read
Gaming & Esports
Gaming & Hardware Hub
PC & Silicon9.3
Frame Generation Input Latency Teardown and Why 120 Generated FPS Can Feel More Sluggish Than 60 Native FPS
A physics-level breakdown of optical flow interpolation, frame pacing queues, display scan-out timing, and the measurable input lag penalty of DLSS 3, FSR 3, and AFMF.
Abhijit•11 min read
Featured Video


Reviews
8.9
Technology
Semiconductor Fabs in India: Dholera, Sanand, and Assam Manufacturing Realities vs Global Foundries
Abhijit•12 min read
8.7
Technology
Wi-Fi 7 Router Guide for India Covering 6 GHz Spectrum, MLO Latency, and Brick-Wall Penetration
Abhijit•10 min read
8.5
